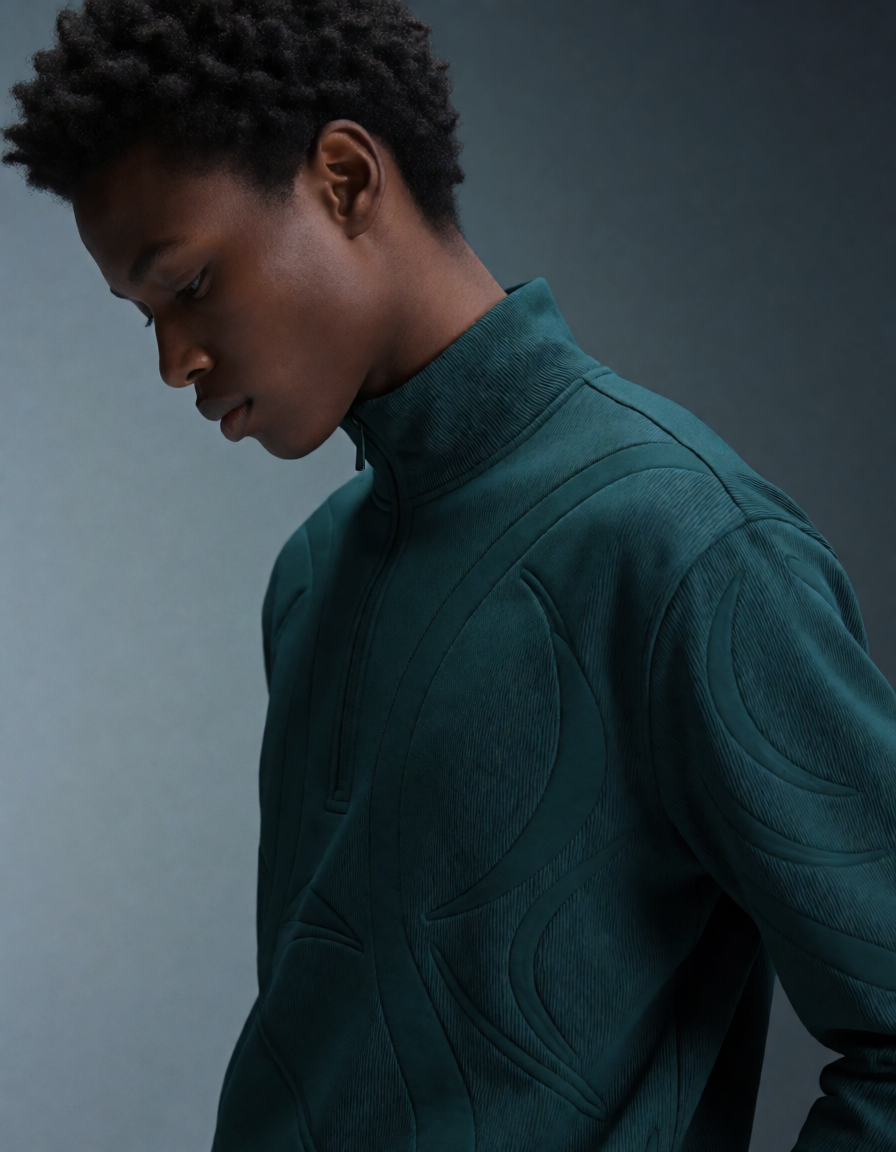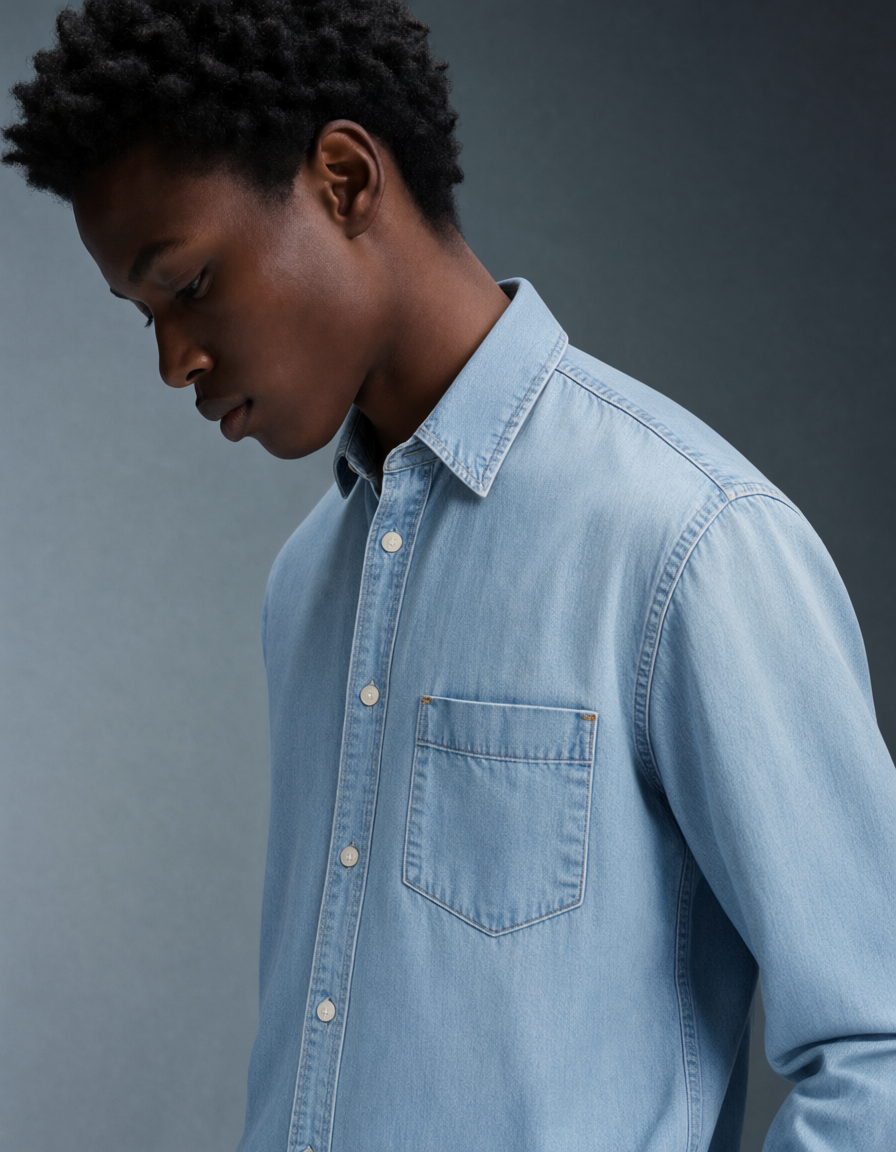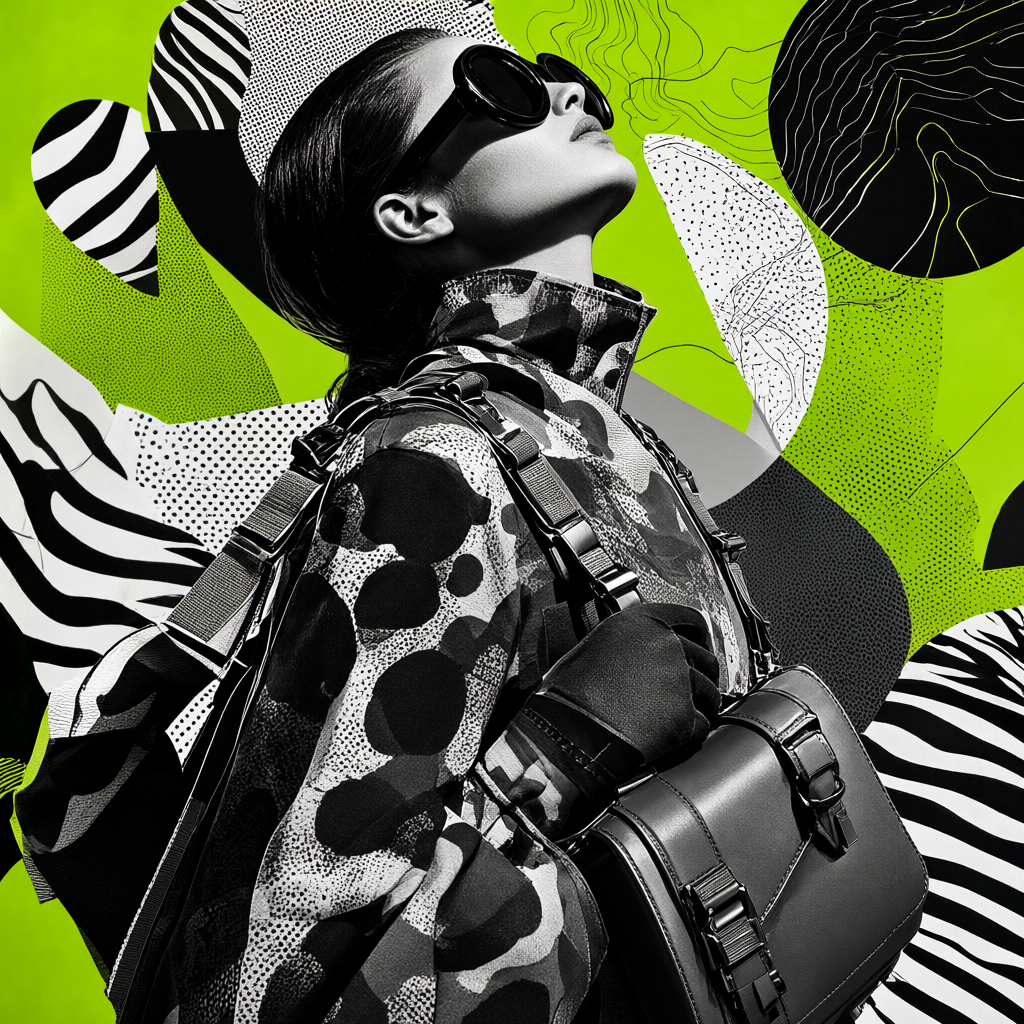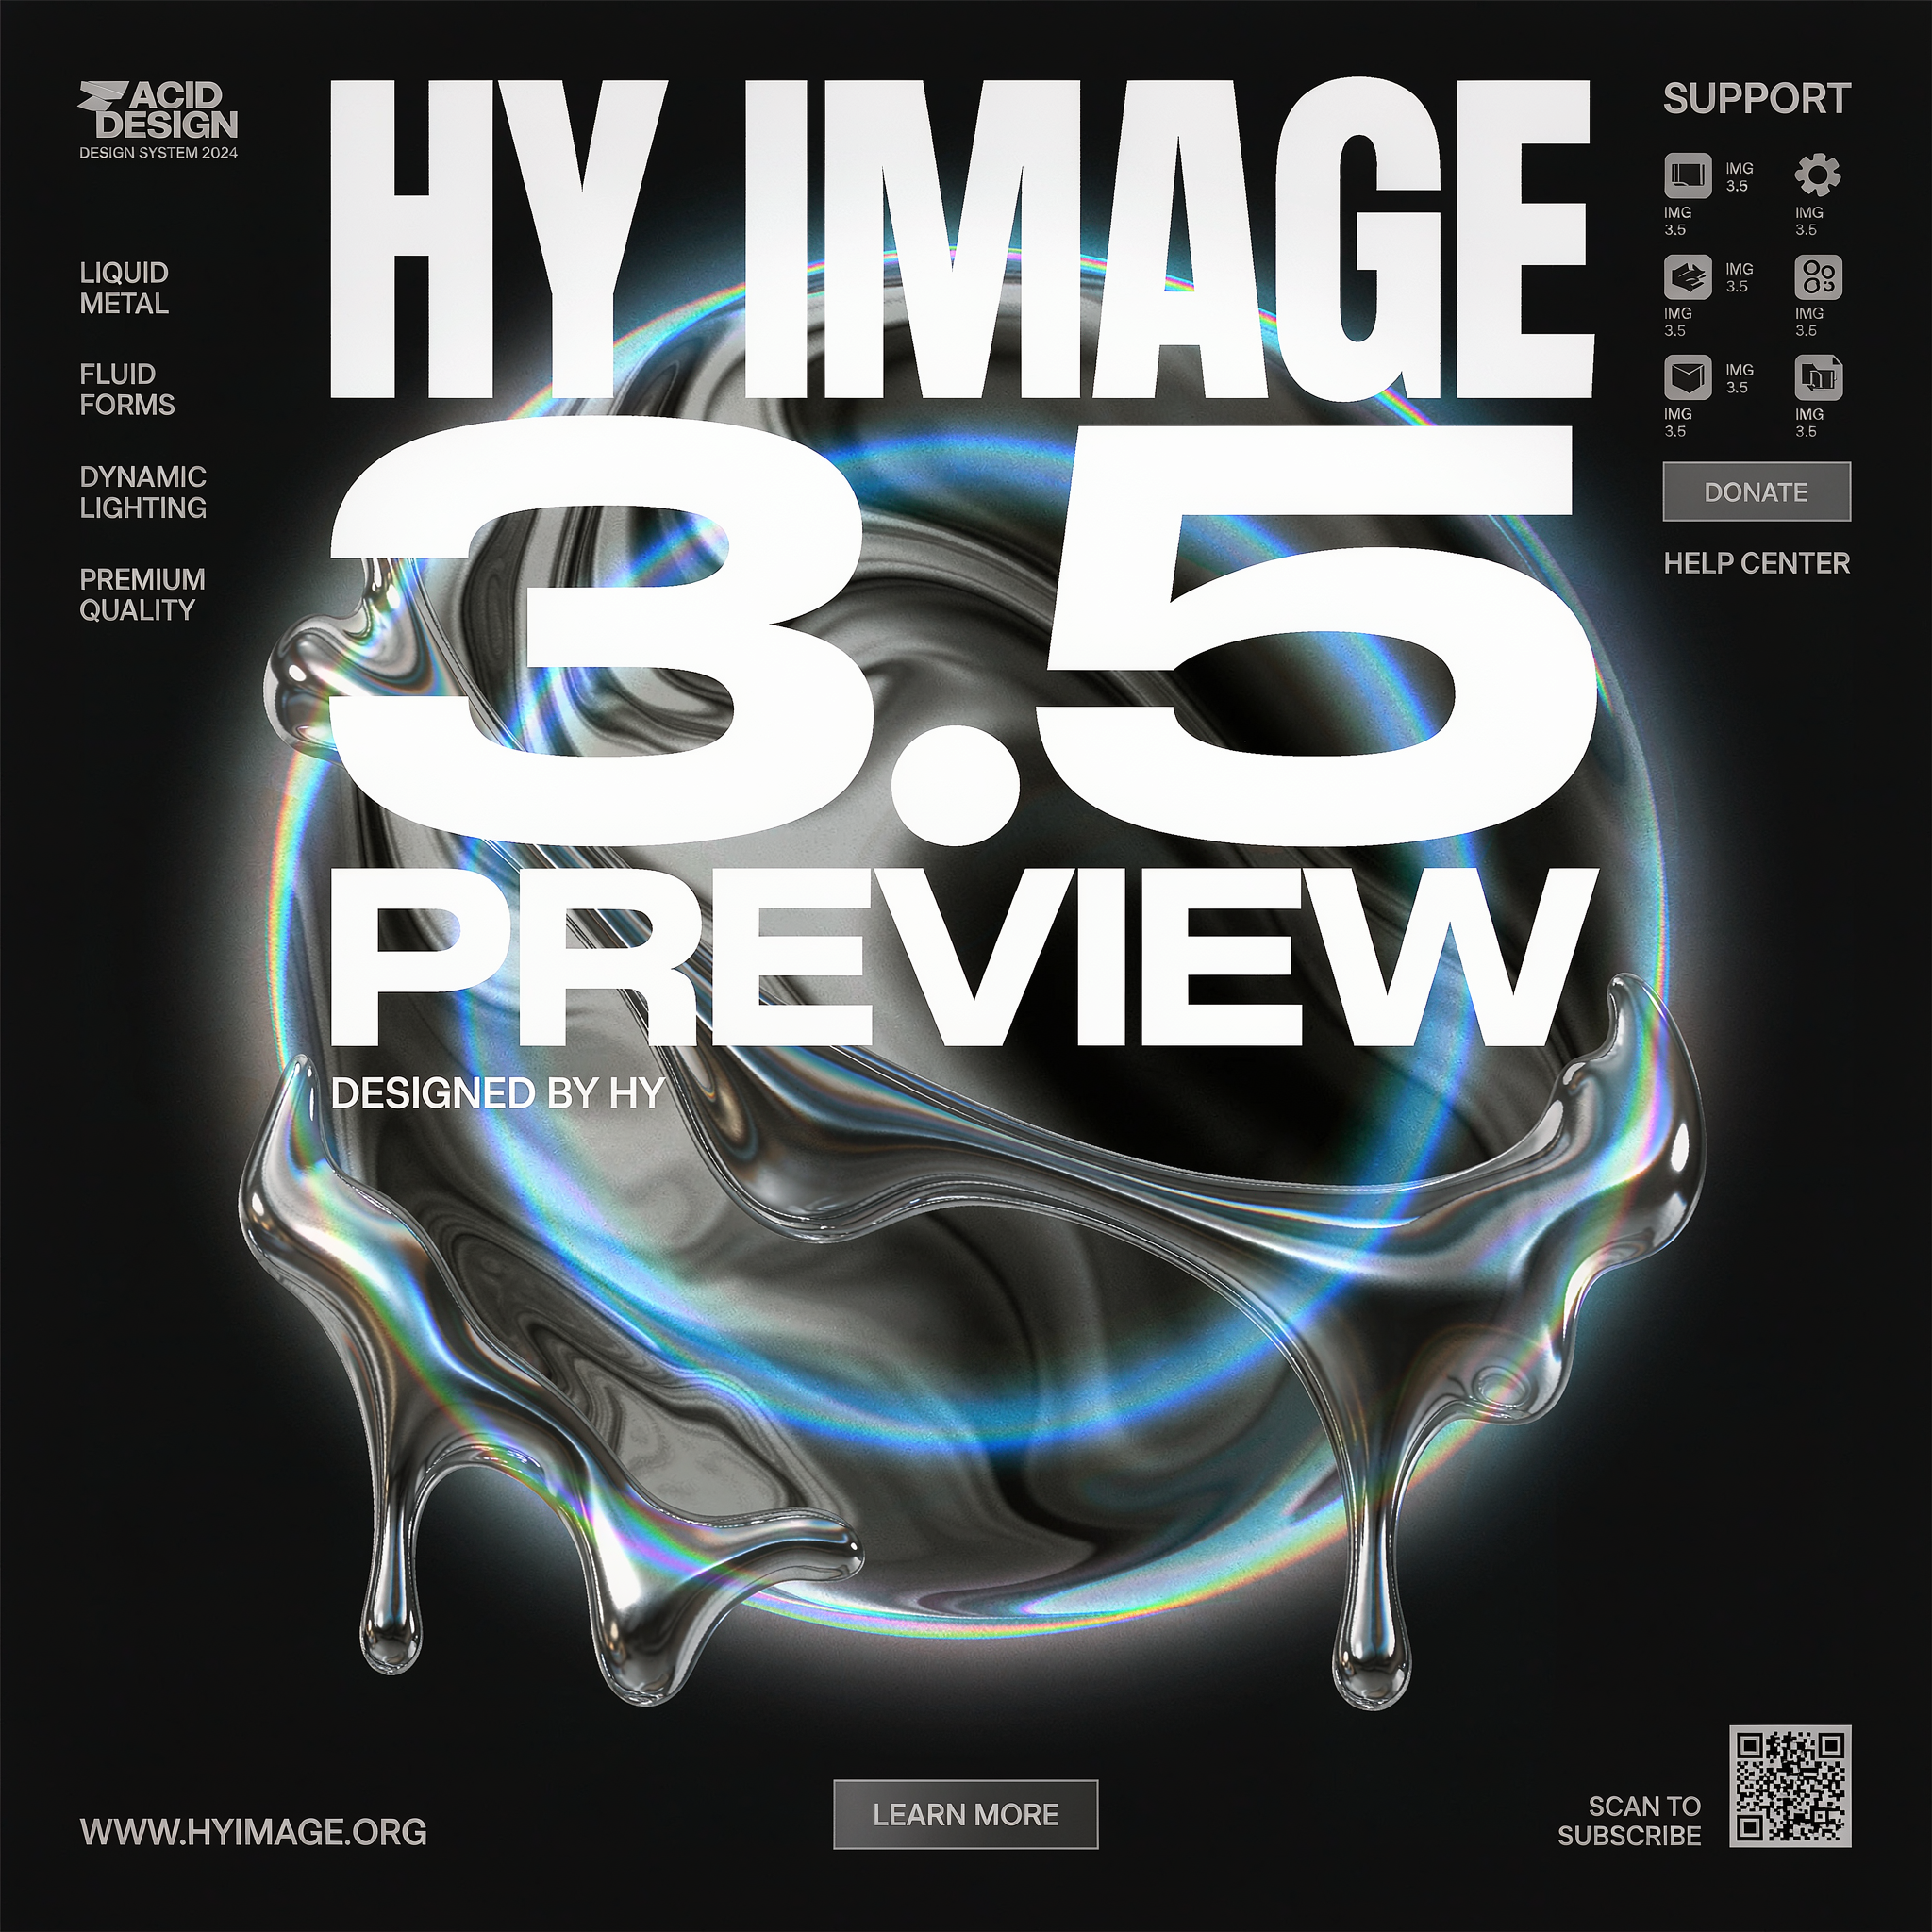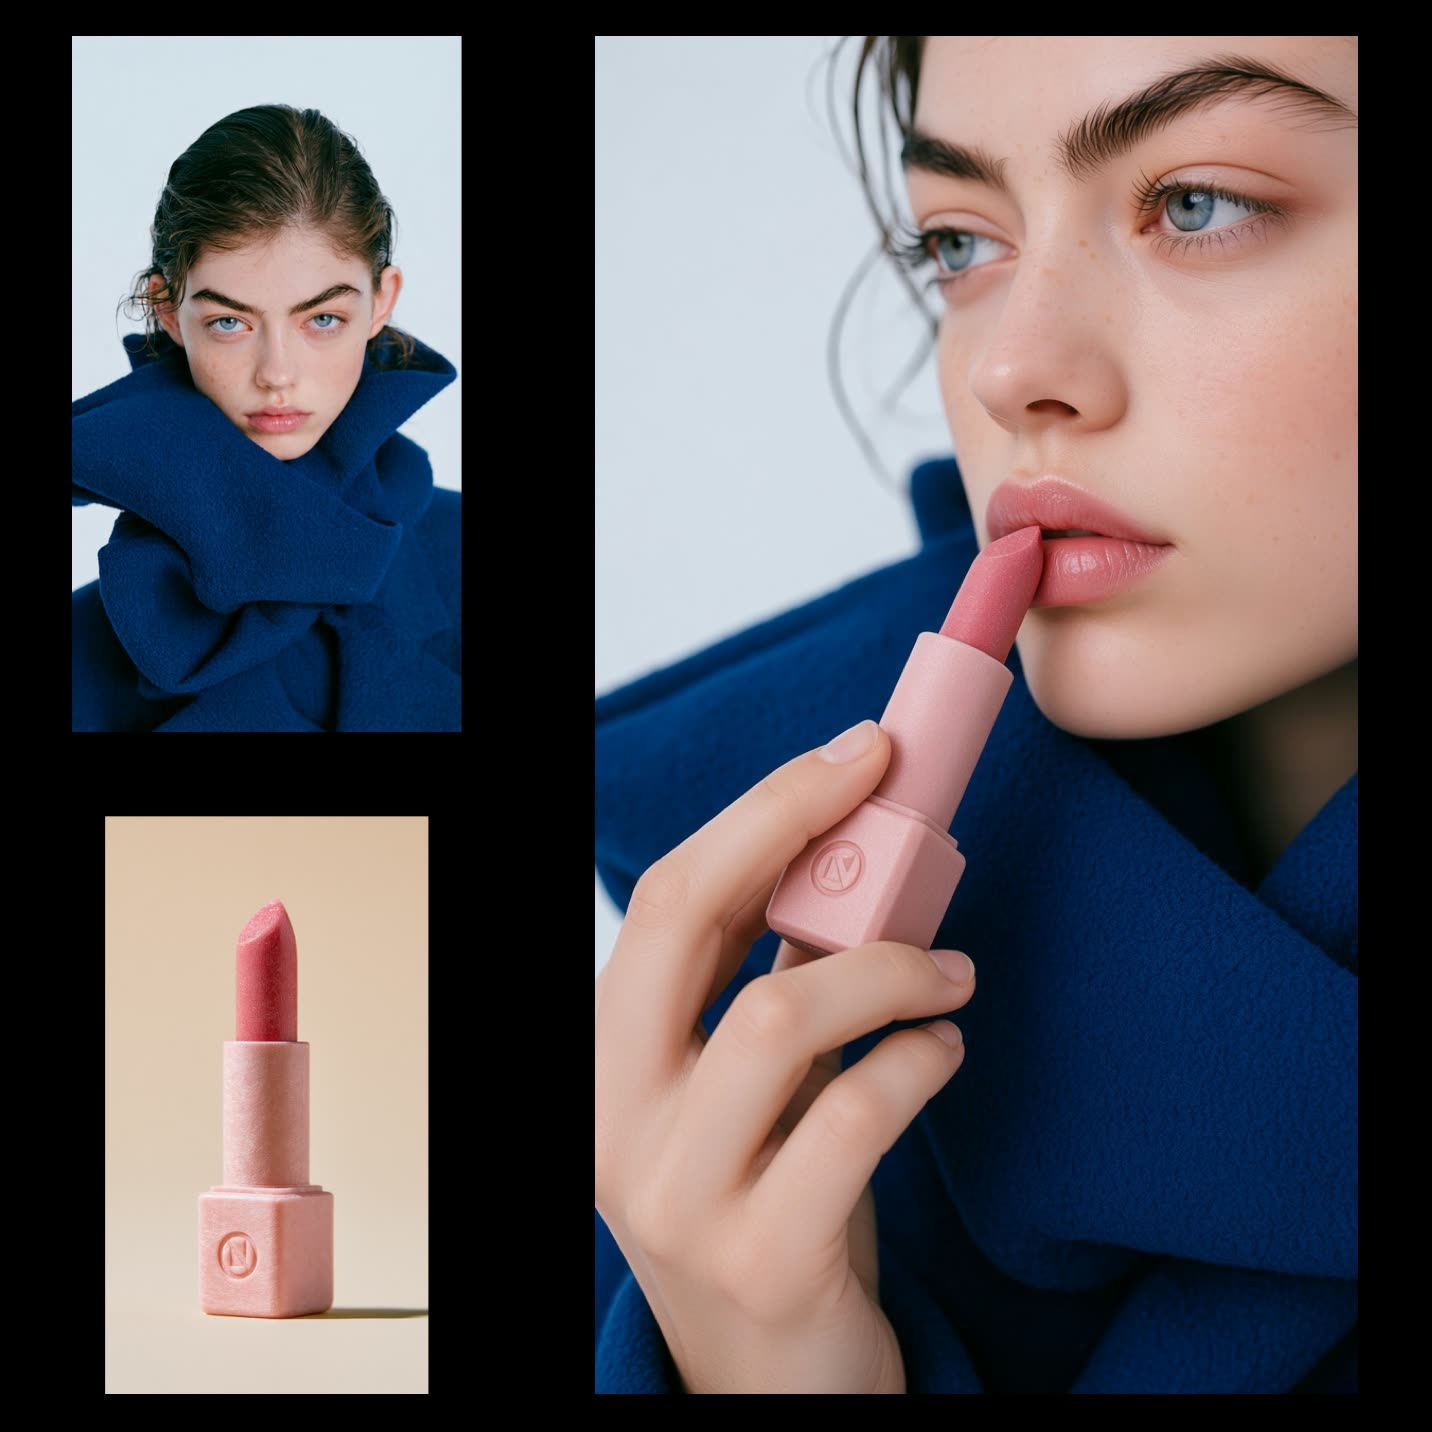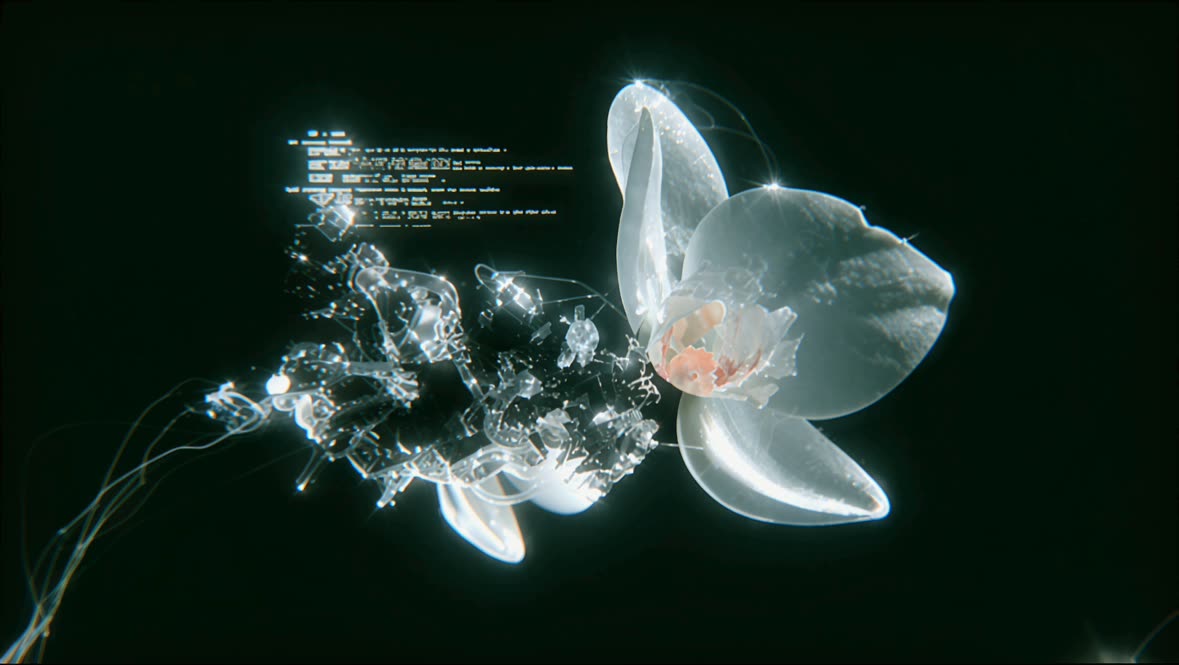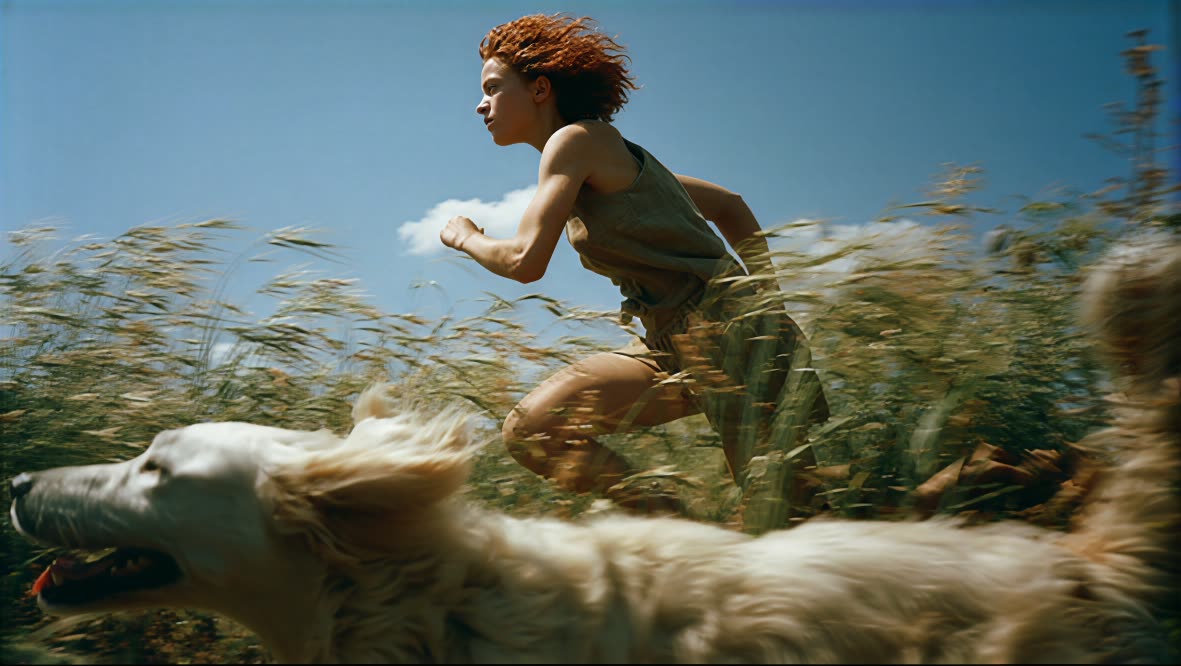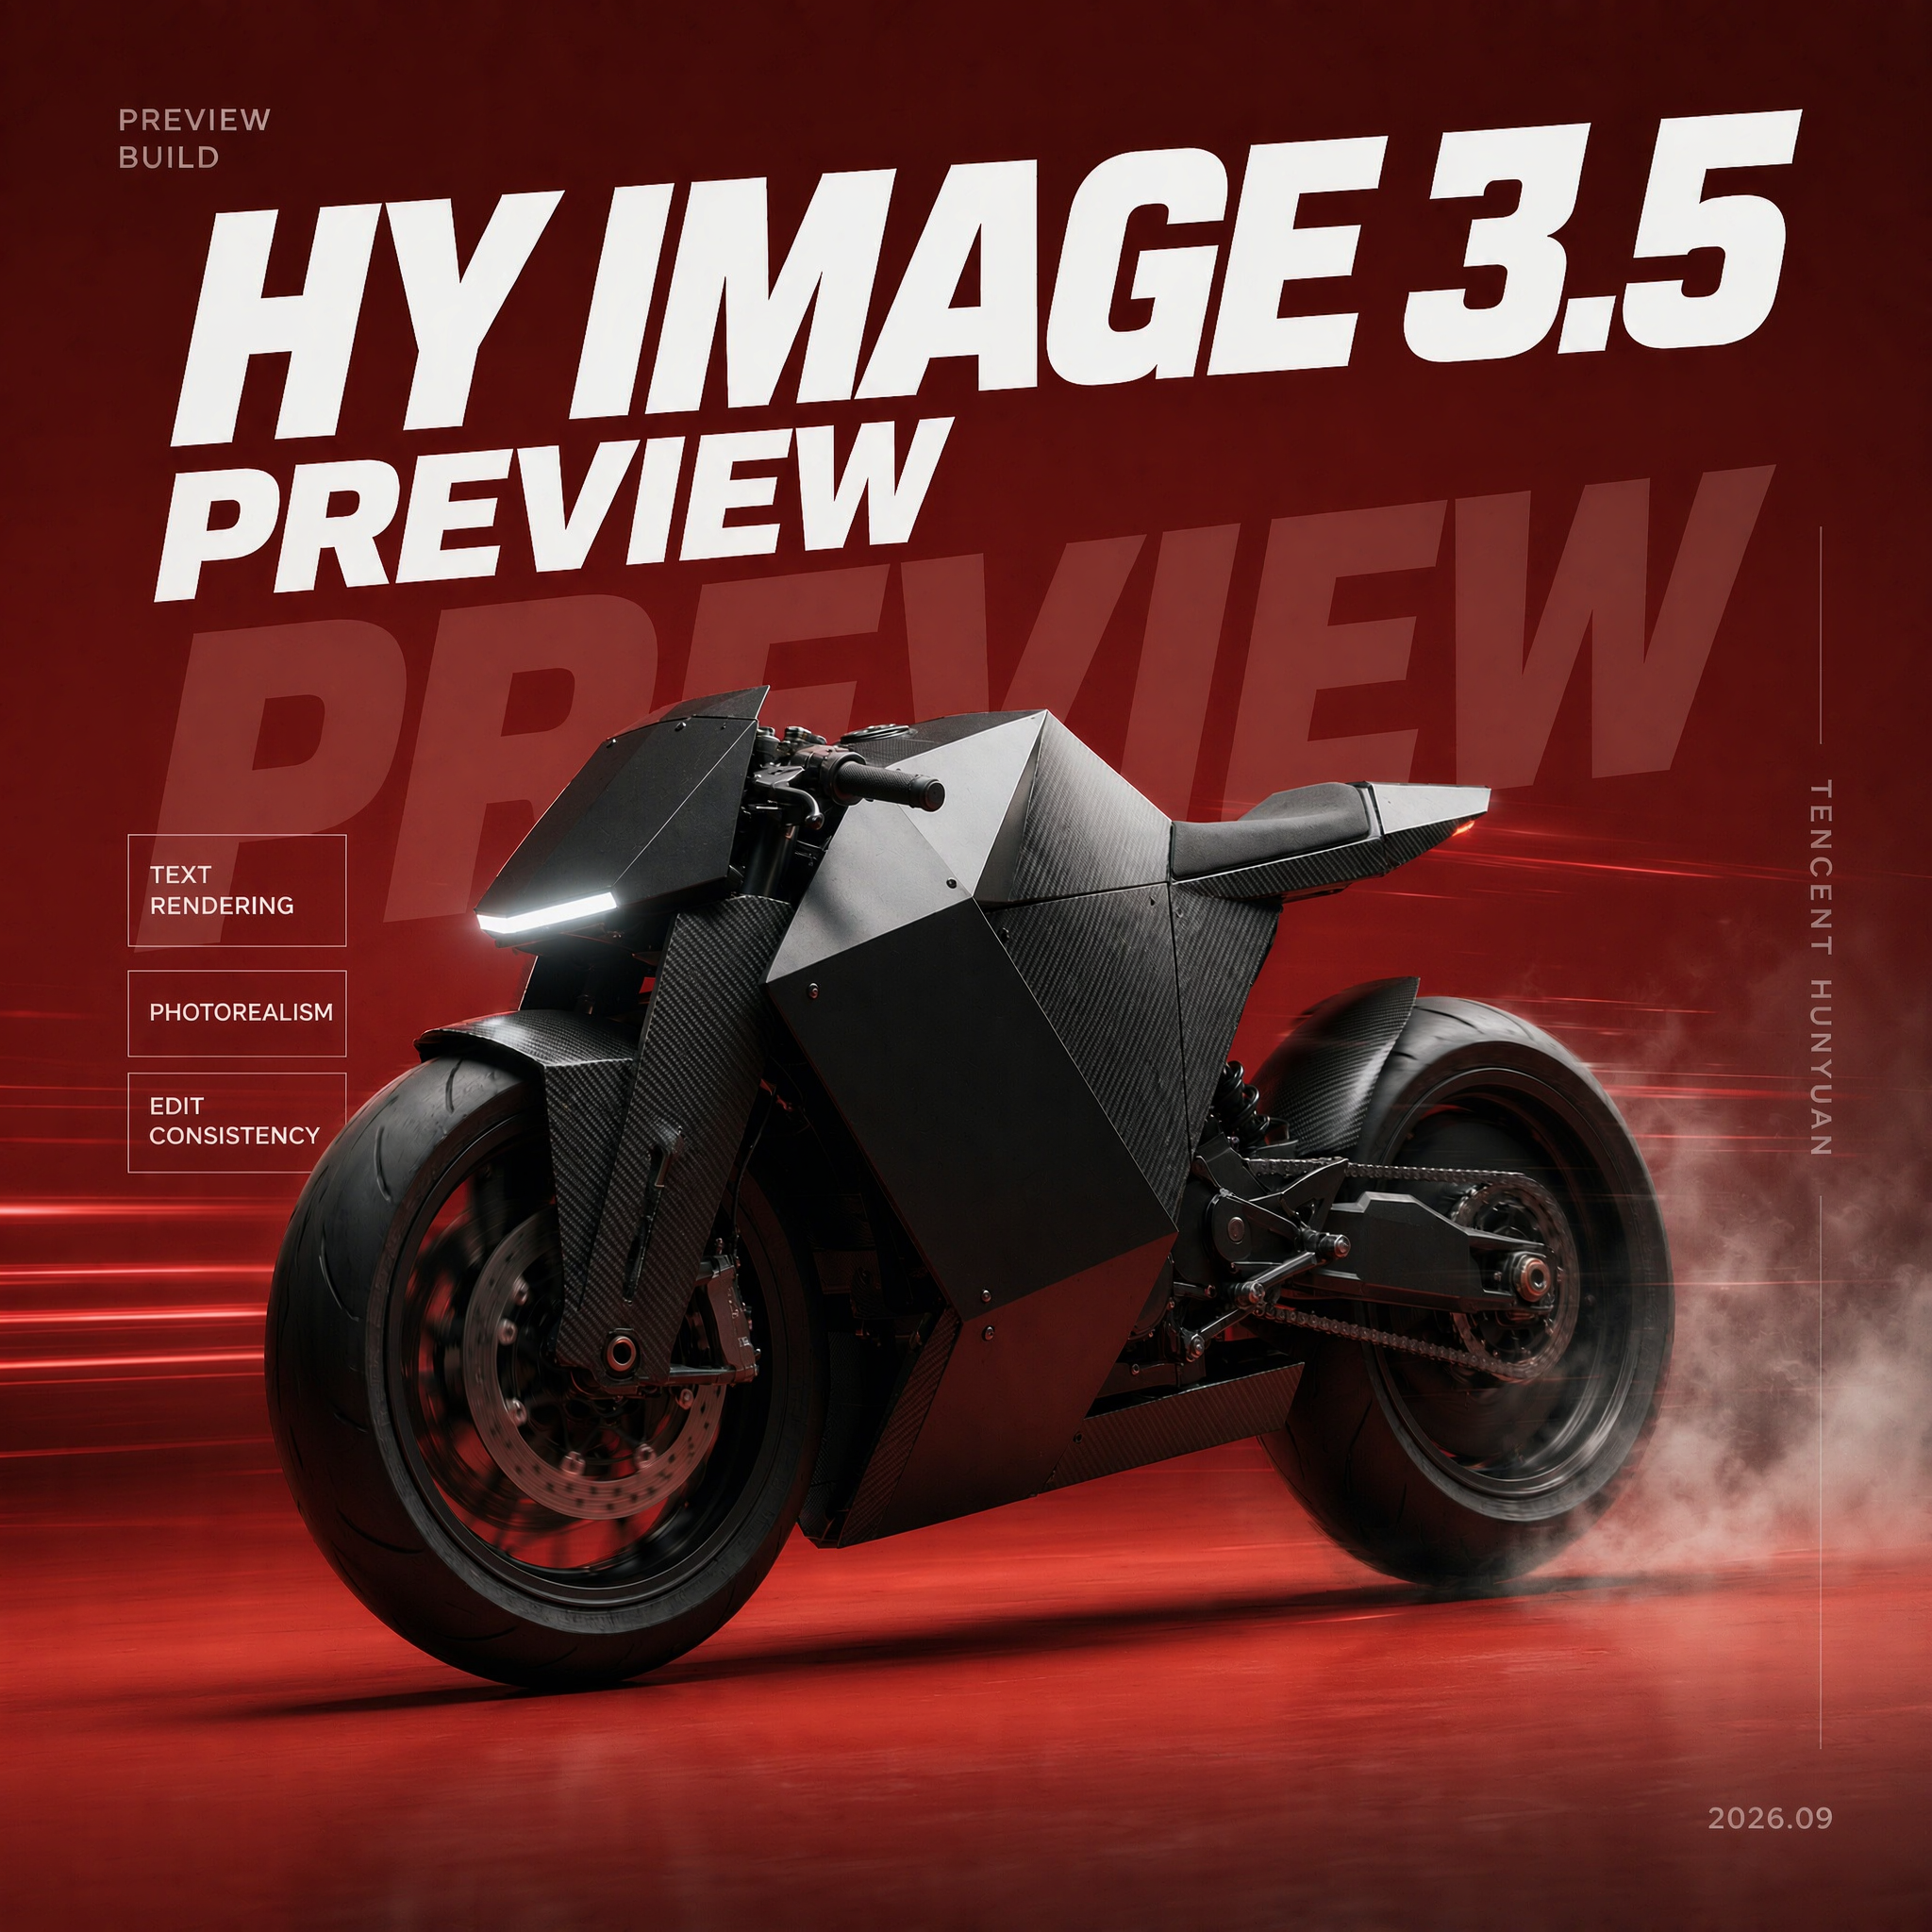
This workflow demonstrates prompt-guided image editing with the HY Image 3.5 Preview model using ComfyUI. It takes one source image, interprets a natural‑language instruction, and returns a single edited image. The core of the graph is the HunyuanImageEditApi node, which sends your image and prompt to the HY Image 3.5 Preview service for multimodal understanding and edit synthesis. LoadImage brings your source (for example, the provided futuristic_brutalist_motorcycle.png), and SaveImageAdvanced writes the result to disk with your preferred filename and format. A MarkdownNote in the canvas provides quick inline tips and links.
Technically, the workflow preserves the input image as a visual anchor while the HunyuanImageEditApi aligns your text prompt to the existing scene. This lets you direct high‑level changes (materials, colorways, backgrounds, lighting, mood) without manually masking or compositing. Because the inference runs through an API, you get consistent edits without managing local model weights, and SaveImageAdvanced gives you control over output naming, format, and quality for production handoff. It’s a practical setup for portrait cleanup, product/hero image variations, and fast turnarounds on marketing visuals.
API
從程式碼使用此工作流
每個 Comfy 工作流都是一個 JSON 圖。下方的 payload 就是此工作流,與 ComfyUI 執行時完全相同 — 你可以從此 URL 取得、放入版本控制,或在 ComfyUI 載入並逐節點執行。
使用 Comfy SDK 以 TypeScript 或 Python 執行。相同程式碼可用於 Comfy Cloud 或你自架的 ComfyUI — 只需更改 base URL。
// Install (beta)
npm i @comfyorg/sdk

// Run this workflow (TypeScript)
import { Comfy } from "@comfyorg/sdk";

const client = new Comfy({ apiKey: "comfyui-..." });
const wf = await client.workflows.fromFile("workflow_api.json");
const job = await client.run(wf);
await job.getOutputs("<output-node-id>")[0].toFile("output.png");
SDK 需使用 API 格式的工作流:請在 ComfyUI 開啟此工作流,並使用 檔案 → 匯出工作流(API)。