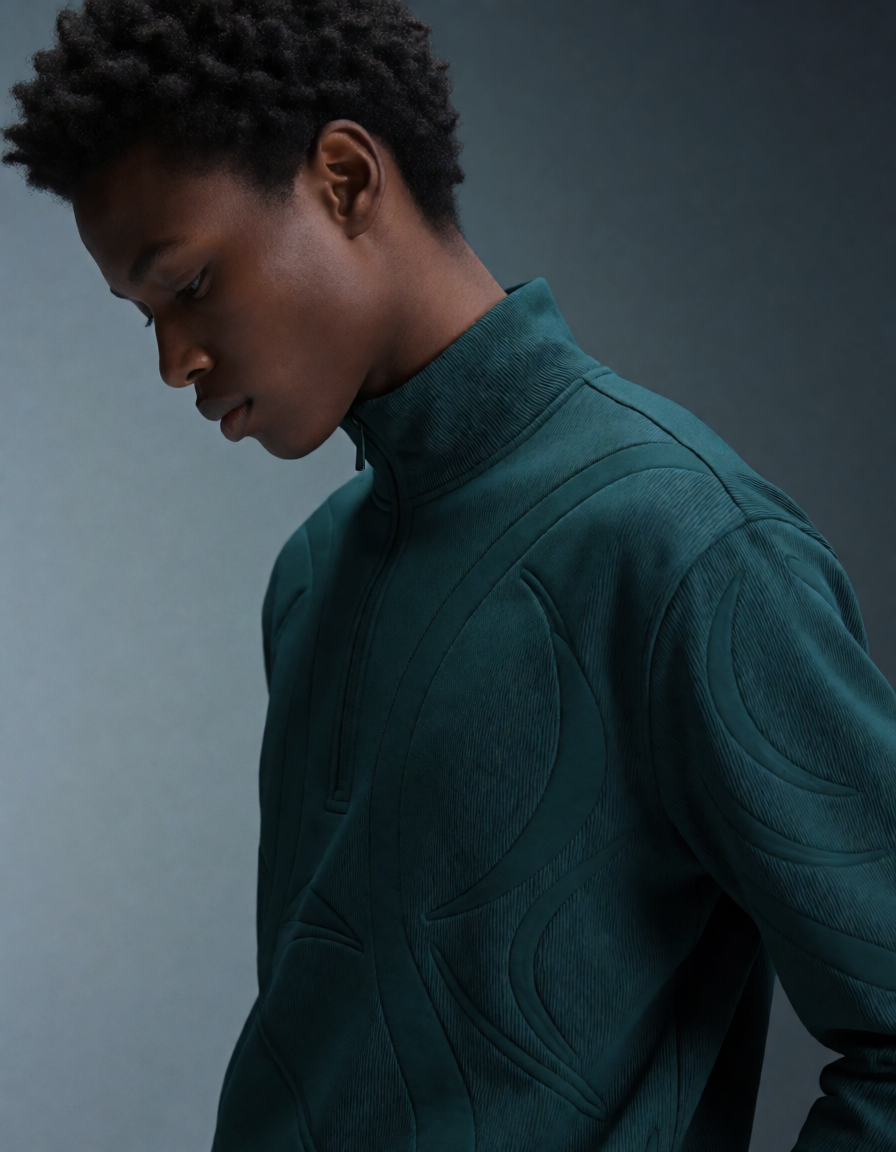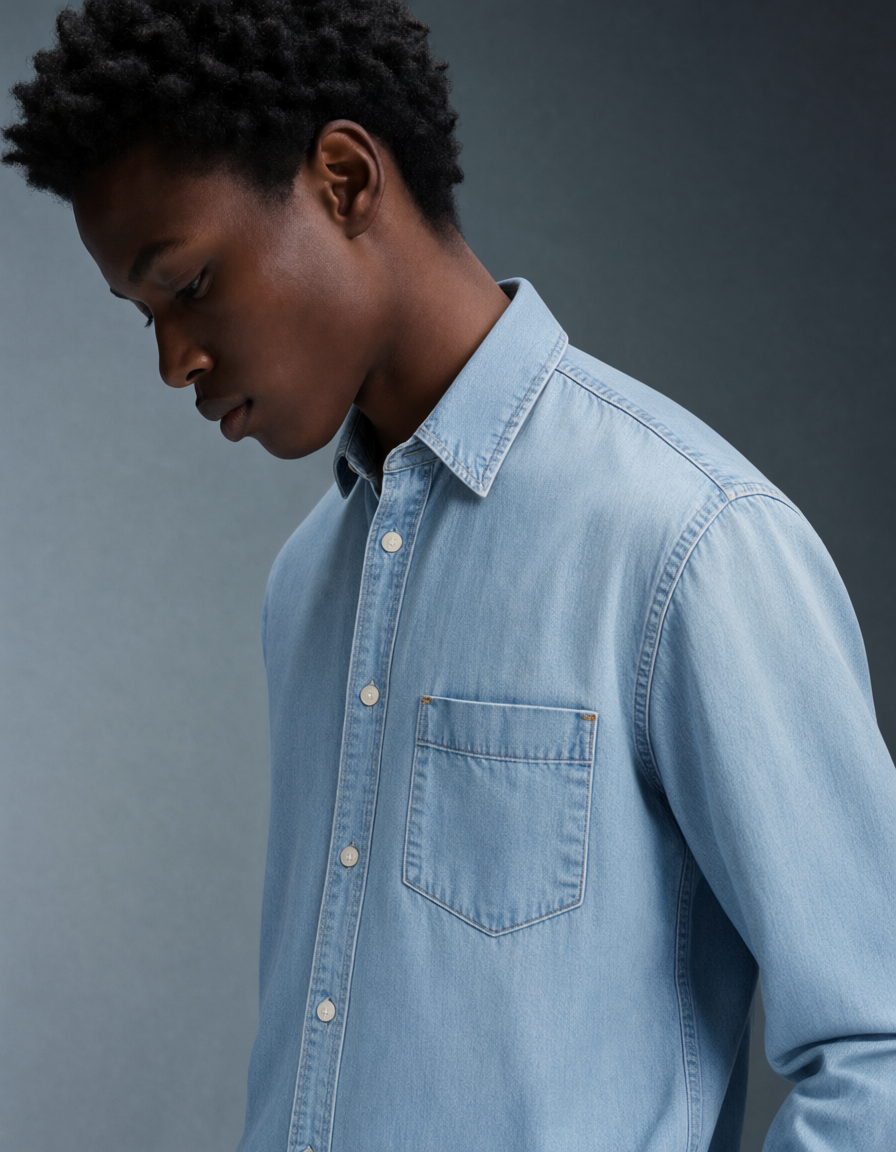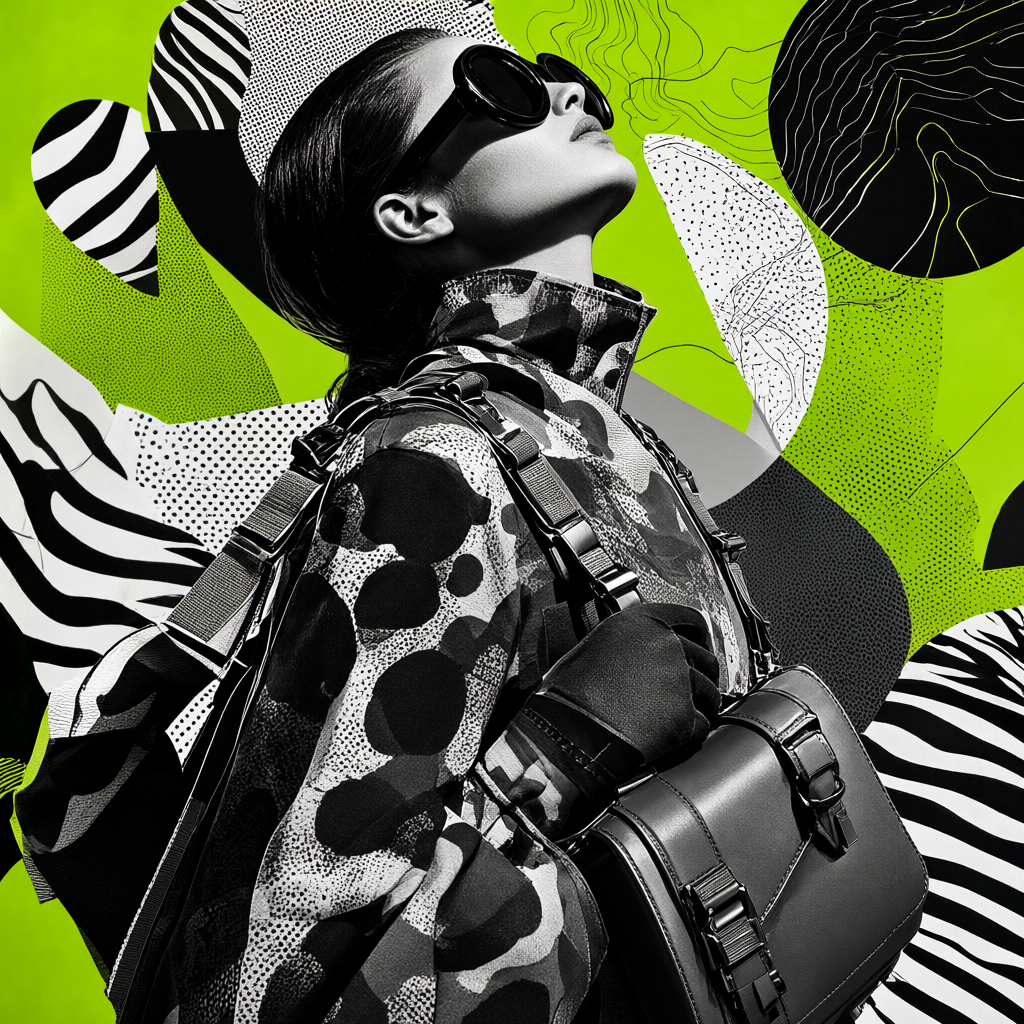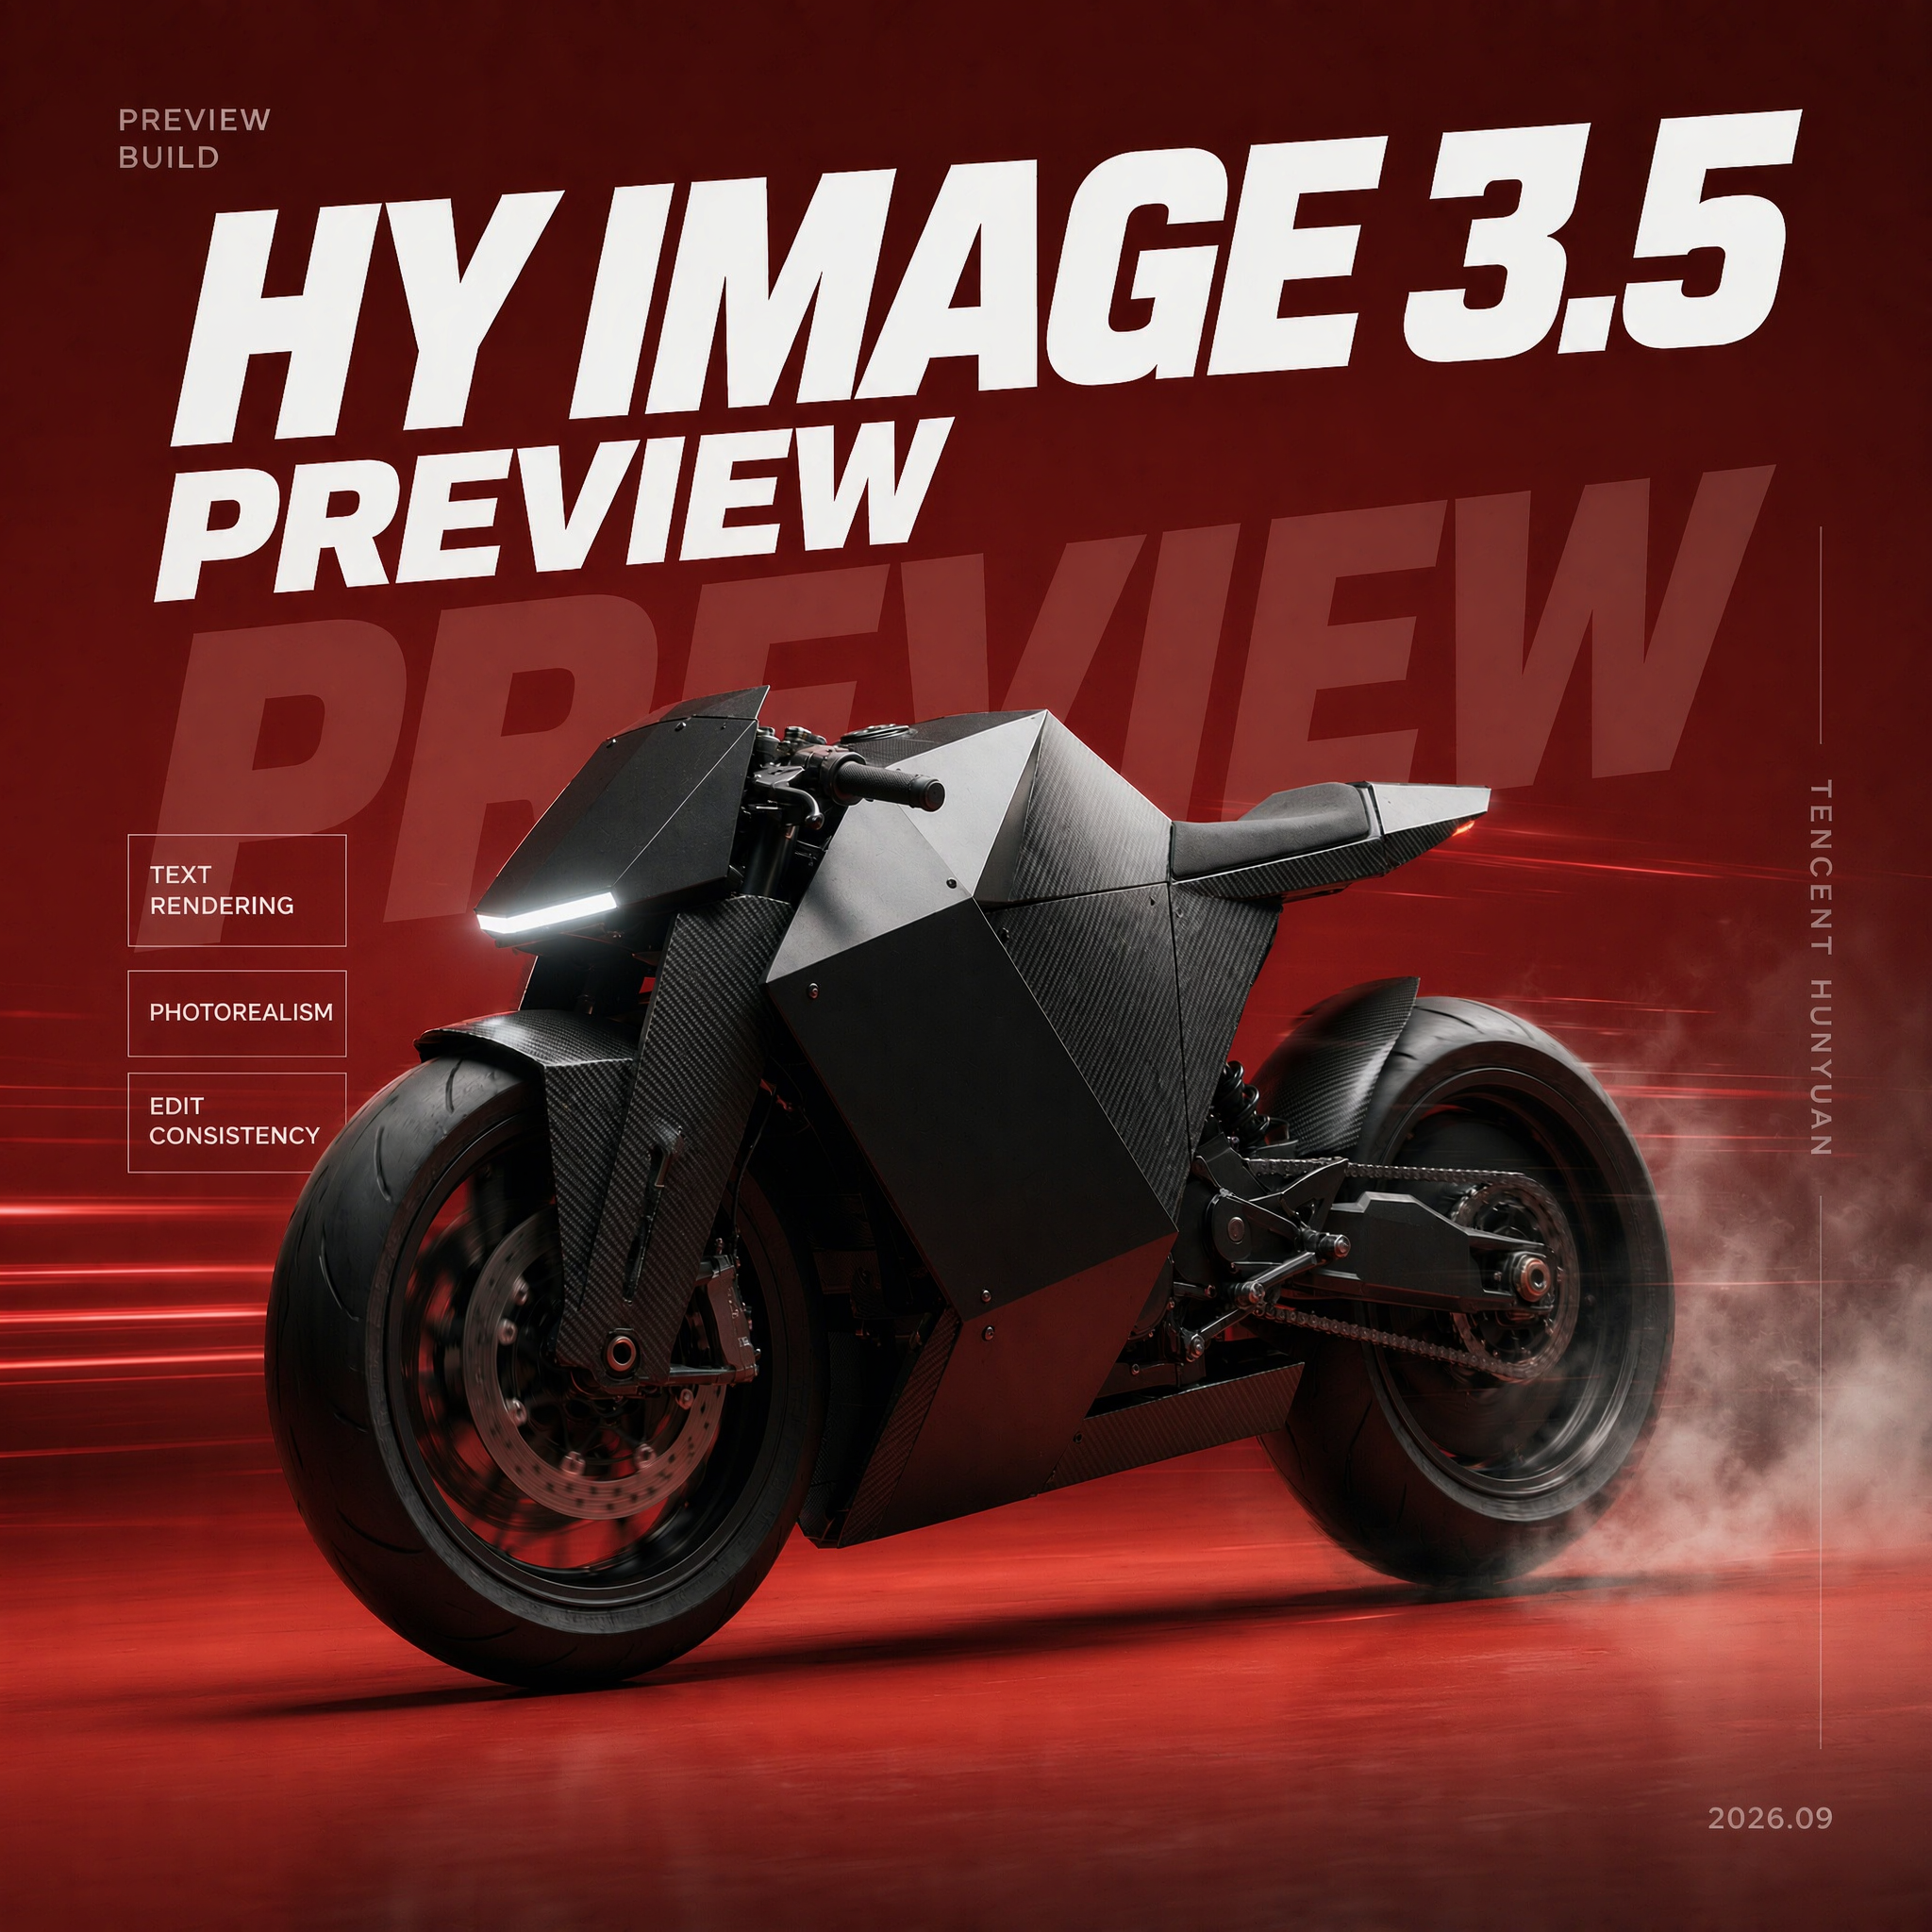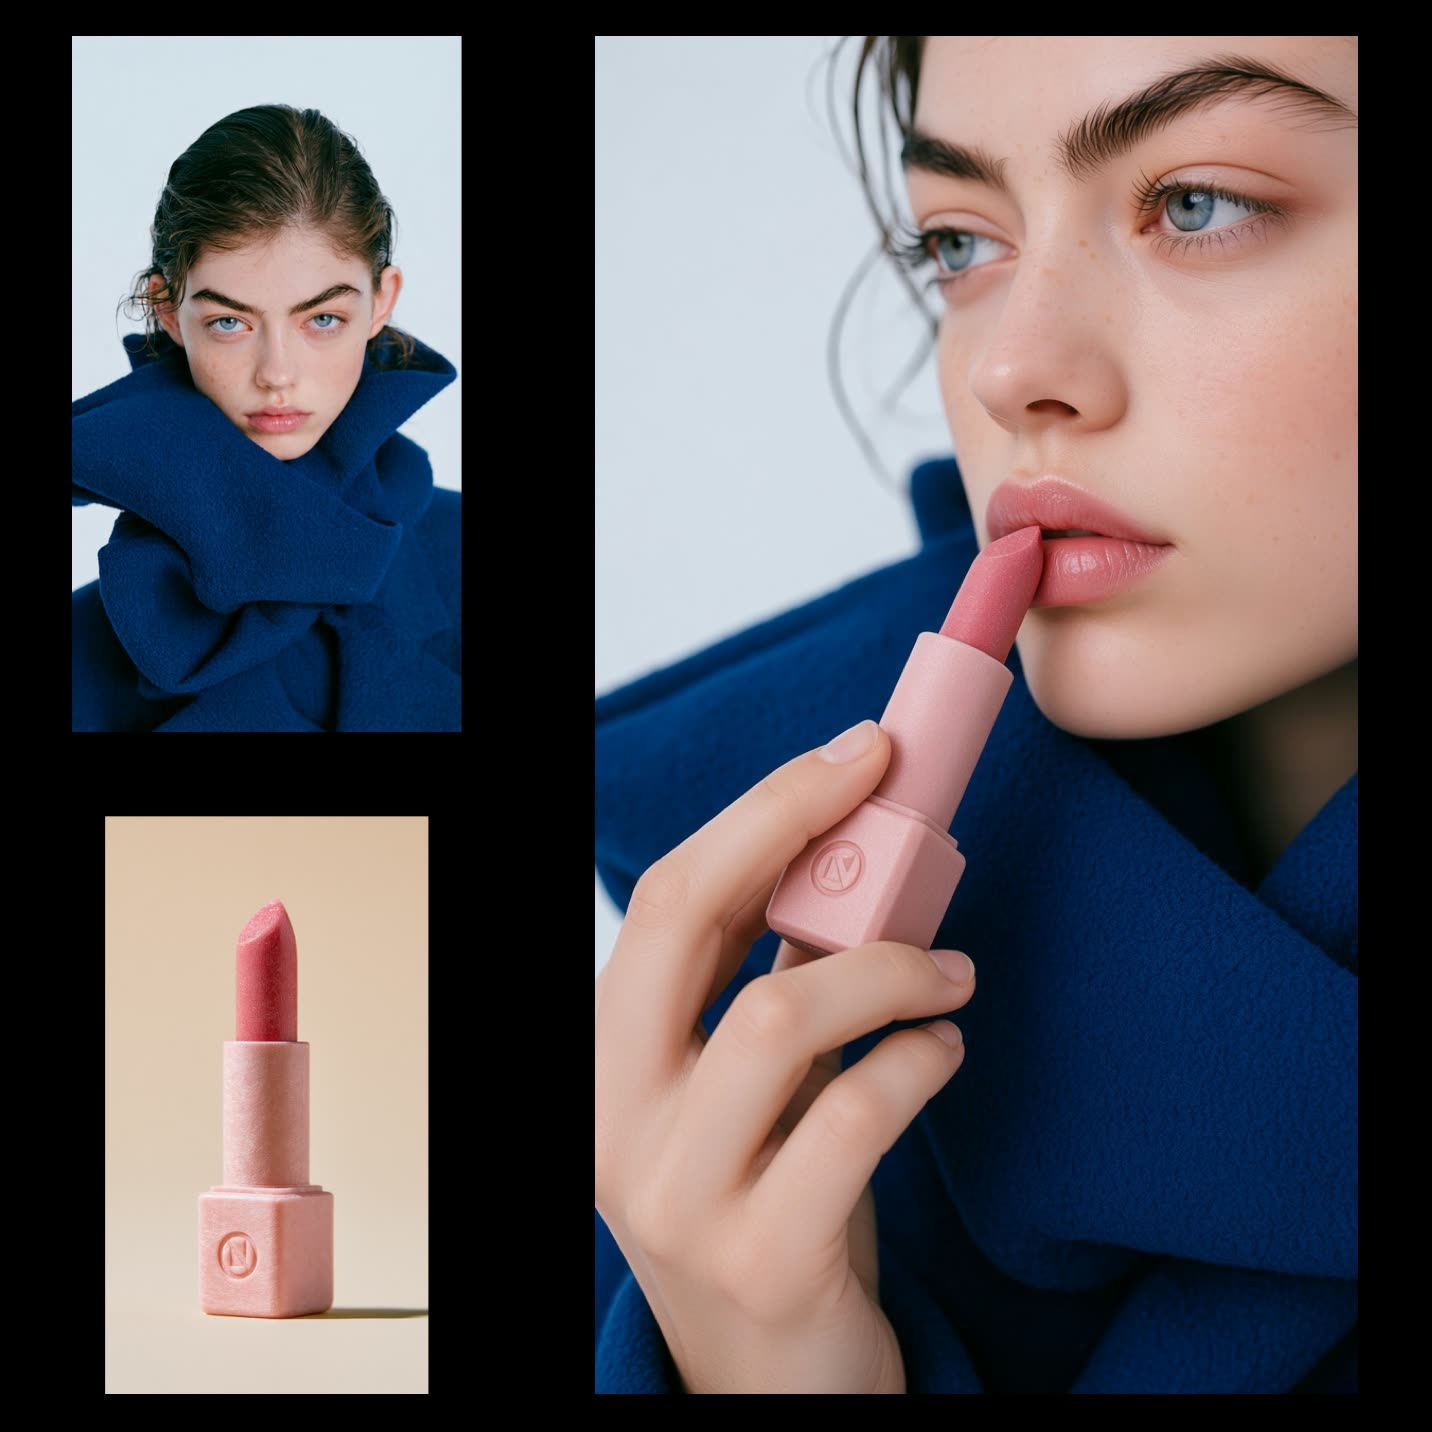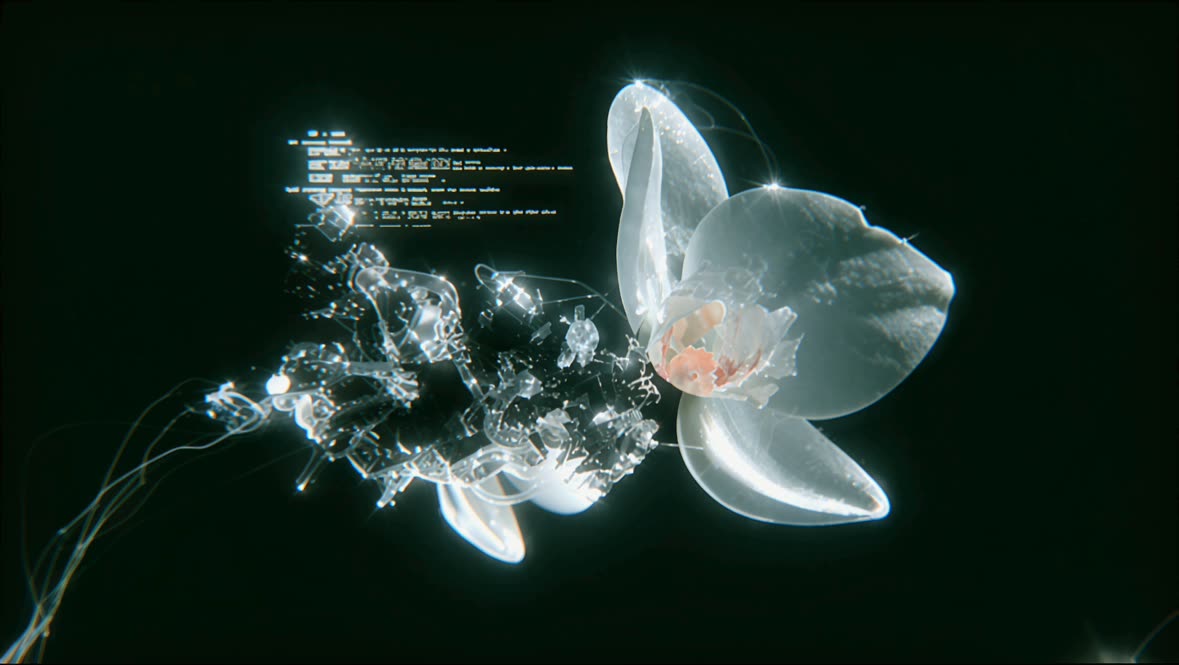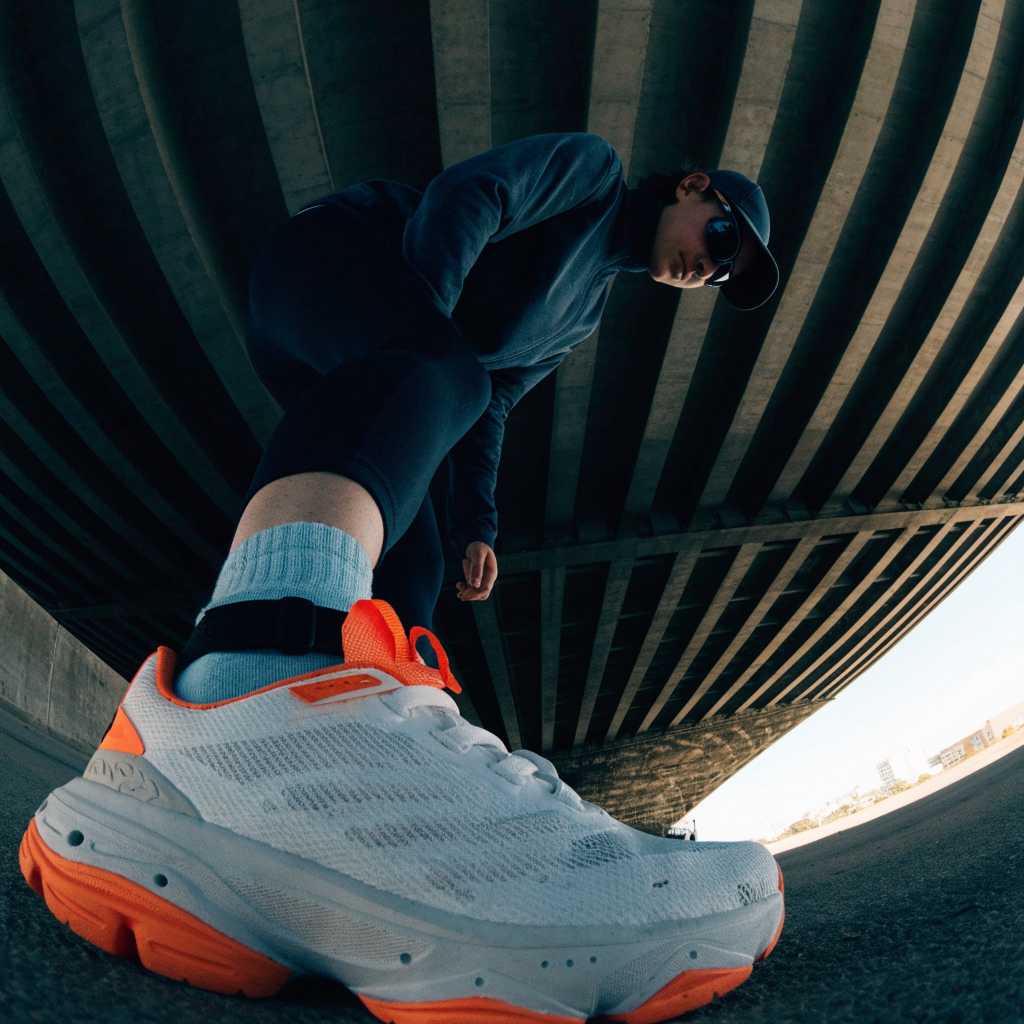
This minimal, fast text-to-image workflow uses the RecraftV4TextToImageNode to call the Recraft V4.1 Flash model and return a single image from your prompt. It’s designed for speed and low cost, making it ideal for rapid iteration, high-volume generation, photography/portrait drafts, atmospheric scene ideation, and quick logo concept exploration. There are no file inputs—just write a prompt, run the node, and get one image back.
Technically, the RecraftV4TextToImageNode serializes your prompt and sends it to the Recraft API for inference with the V4.1 Flash backend, then outputs a ComfyUI image tensor. That tensor flows directly into SaveImage, which writes the result to your ComfyUI/output directory using the filename prefix and format set in the node. Depending on the node’s implementation, you may also have common controls (such as image size and seed). Because the workflow produces exactly one image per execution, it’s straightforward to queue many runs for A/B testing or bulk prompt variations.
API
從程式碼使用此工作流
每個 Comfy 工作流都是一個 JSON 圖。下方的 payload 就是此工作流,與 ComfyUI 執行時完全相同 — 你可以從此 URL 取得、放入版本控制,或在 ComfyUI 載入並逐節點執行。
使用 Comfy SDK 以 TypeScript 或 Python 執行。相同程式碼可用於 Comfy Cloud 或你自架的 ComfyUI — 只需更改 base URL。
// Install (beta)
npm i @comfyorg/sdk

// Run this workflow (TypeScript)
import { Comfy } from "@comfyorg/sdk";

const client = new Comfy({ apiKey: "comfyui-..." });
const wf = await client.workflows.fromFile("workflow_api.json");
const job = await client.run(wf);
await job.getOutputs("<output-node-id>")[0].toFile("output.png");
SDK 需使用 API 格式的工作流:請在 ComfyUI 開啟此工作流,並使用 檔案 → 匯出工作流(API)。